Vector Database Practices for ChatGPT: OpenAI’s announcement of GPT-5 on August 15, 2026, featured native vector database integration. That shift made raw memory retrieval a core engine capability instead of an afterthought.
Engineering teams managing enterprise plugins now need stricter operating standards. Without optimised retrieval pipelines, even frontier models can suffer latency spikes and hallucination loops. Here’s how leading infrastructure providers are adapting to this new reality.
Vector Database Practices: The Shift From Passive Storage To Active Retrieval
Before mid-2026, developers treated vector stores as passive storage layers. Rigid hardware requirements and high query latencies often created bottlenecks. Milvus 3.0, launched on July 22, 2026, exposed those older limits by requiring at least 64 GB RAM and 8 vCPUs for optimal sharding with OpenAI embedding models.
Teams running older deployments suddenly faced compute costs that dwarfed model inference expenses. Later, Weaviate announced its hybrid search optimization update on September 28, 2026. The update cut latency to under 15 milliseconds for 1,536-dimensional vectors, showing that static indexing no longer worked for real-time interactions.
Critical Performance Benchmarks And Infrastructure Demands
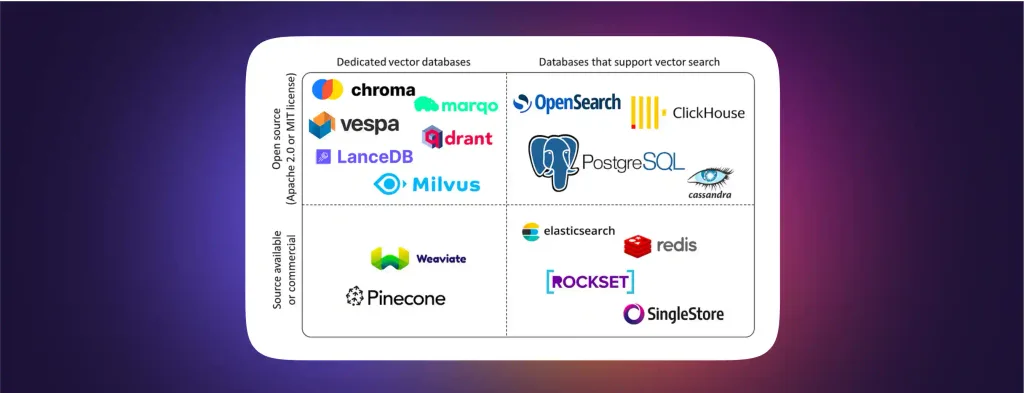
Effective vector database practices center on three non-negotiable needs: dedicated throughput allocation, aggressive index pruning, and reliable automated snapshots. First, enterprise workloads need burst capacity that matches model demand. Pinecone introduced Serverless Index v2 on September 10, 2026, offering dedicated throughput of up to 100,000 queries per second for ChatGPT enterprise plugins.
Second, controlling costs means shrinking the footprint of high-dimensional graphs. Qdrant released version 1.12 on October 1, 2026, cutting memory overhead for hnsw graph indexes by 35% on standard AWS c6i.16xlarge instances. That lets teams run denser retrievals without increasing their cloud bills.
Finally, data persistence needs to run on its own. Chroma deployed its managed cloud tier on August 5, 2026, supporting up to 10 million vector embeddings per collection with automated daily snapshots to AWS S3. This removes the manual backup burden from AI engineers.
Vendor Trade-offs And Security Considerations
The market now sits between specialized throughput leaders and flexible open-weight ecosystems. Some architects say proprietary serverless layers like Pinecone lock teams into vendor-specific tooling, which limits cross-platform portability. Others argue that managing distributed hnsw shards across multiple regions is harder than using a self-hosted solution.
When weighing these options, remember that Chroma’s managed tier favors easy deployment over granular tuning. Qdrant requires more configuration expertise, but it delivers superior memory density.
External guides such as Towards Data Science explain architectural patterns for these integrations, though implementation details vary by provider.
| Provider | Key Update | Metric Gain | Best Use Case |
|---|---|---|---|
| Pinecone | Serverless Index v2 | 100k QPS throughput | Enterprise plugin bursts |
| Qdrant | Version 1.12 | 35% memory reduction | Cost-sensitive hnsw loads |
| Weaviate | Hybrid Search Opt | Real-time 1536-dim queries | |
| Chroma | Managed Cloud Tier | 10M embeddings/collection | Rapid prototyping & backups |
Selecting The Right Stack For Production Workloads
If you need to handle massive numbers of concurrent sessions without tuning infrastructure, Pinecone’s dedicated throughput offering provides the most reliable ceiling for production environments. Teams balancing memory costs with dense retrieval needs will likely get the best efficiency ratio from Qdrant’s latest optimizations.
Projects that need quick iteration and simpler data lifecycle management should choose Chroma’s managed approach. Vector stores will become even more important stability anchors as OpenAI Mitigates ChatGPT service errors. Choose based on workload volume, not feature lists alone.
Was this article helpful?
Your feedback directly improves future articles on this site.