MEX-W
 ARG-W
 ARS2
 EVE0
 COV0
 FUL1
 OFC0
 NEU0
 NEOM2
 ABH0
 RAC0
 ESP1
 KHO0
 ETT0
 BLK2
 WXM0
 NAP
 ROMA
 CHE
 TOT
 VAL
 VIL
 DOR
 SGE
 RIY
 TAA
 LAZ
 PAR
 RCL
 PAR
 FCA1
 FCU1
 KOE0
 S040
 M052
 SVW3
 RBL4
 ELV0
 KNGHT74/1 (12.1/20 ov)
 MPUMA
 NZ-A135/3 (41 ov)
 IND-A113
 SYL
 KHU
 MYMS299/4 (87 ov)
 CHATT
 DHA293/3 (84.1 ov)
 RAJ
 RAN320/5 (80 ov)
 BAR
 UAE
 NED
 PAK
 ENG
 IND-W
 ZIM-W
 GMB
 LES
 MOZ
 ZMB
 NGA
 UGA
 NAM321/6
 IRE290 (47.3/50 ov, target 322)
 NZ180/5
 IND181/6 (19.5 ov)
 CAR1
 BIR0
 LCN4
 BUR1
 PNE1
 WBA1
 QPR4
 SWA0
 STK0
 BRC0
 ATM
 DEP
 SCP1
 HSV0
 CAG0
 BOL2
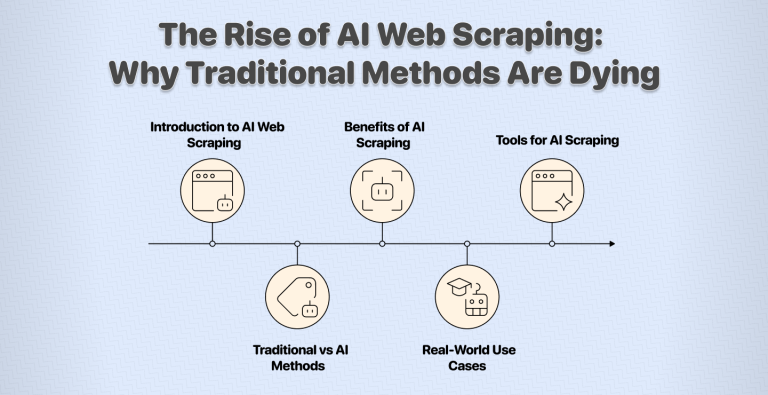
A hot laptop fan, a blinking cursor, and then—suddenly—the page content you need lands in a neat JSON file. In a guide from KDnuggets, the approach uses Python to build a simple AI web scraper, turning messy web pages into structured text you can feed into downstream AI workflows. The article is framed around August 14, 2026 (the date is provided for context; the original may have updates).
That’s the practical news: teams keep trying to “just scrape” sites, then get blocked by robots rules, broken selectors, and unstructured HTML. This guide is useful because it keeps the pipeline small—fetch, parse, extract, then optionally summarise or tag—so you can iterate without building an entire crawling platform.
“Start with the simplest scraper you can, then make it smarter once your extraction is reliable.”
Scraping isn’t only an engineering problem; it’s a policy problem too. Before you write code, check whether the target site permits automated access—review its robots.txt and Terms of Service. Also, keep your requests polite (rate limiting) so you’re not hammering servers while debugging. Stay tuned for more on Simple AI Web Scraper.
What You Need: A Simple AI Web Scraper
This scraper approach hinges on a few common Python building blocks: an HTTP client to download pages, an HTML parser to extract elements, and a small “AI layer” of Simple AI Web Scraper to transform extracted text into cleaner output (like summaries or labels). If you’re targeting articles, product pages, or blog posts, you’ll usually want to extract the title, main text, links, and sometimes published date.
The prerequisite is simple: Python installed plus the packages for HTTP requests and parsing. If your environment is already set up for AI work, this will integrate cleanly with model calls or local inference later. If it isn’t, start with extraction first; adding any AI step before you confirm you’re getting correct text is how brittle scrapers get born.
Also, the AI news angle matters because modern workflows increasingly depend on structured text. OpenAI’s documentation and research summaries show the value of turning raw text into consistent inputs for model reasoning and QA (see the OpenAI Blog at https://openai.com/blog). Even if you swap models later, your scraper’s output format should stay stable.
Steps: Build a Simple Python AI Web Scraper
- Pick a single URL type and define the extraction target
Choose one page pattern (for example, an article page) and list what you need. Start with one or two fields—like headline + body text—so you can validate your selectors quickly.
- Fetch the HTML safely
Use Python to request the page content over HTTP. Add headers (like a user-agent) and avoid rapid loops while you’re still testing. This is where most early failures happen—timeouts, redirects, or receiving “access denied” pages.
- Parse HTML and locate reliable elements
Use an HTML parser to navigate the DOM. Identify stable attributes such as headings, article tags, or CSS classes. If the markup is inconsistent, consider extracting by semantic structure.
- Extract clean text and normalize it
Convert HTML into plain text and remove junk like navigation menus or related-post blocks. A simple normalization step—whitespace cleanup, trimming, and removing repeated boilerplate—often improves downstream AI results more than model changes.
- Add a lightweight “AI layer” after extraction
Once the text is correct, you can call an AI step to summarize, classify, extract entities, or produce tags. For context on why structured prompts and consistent input formats matter, check out AI coverage and engineering trends from VentureBeat’s AI category at https://venturebeat.com/category/ai.
- Output structured JSON and log failures
Save results as JSON with explicit keys (e.g. url, title, content, summary). Also log which URLs failed and why—so you can fix selectors without guessing. If you’re experimenting, store “raw extracted text” alongside “final cleaned text” for debugging.
- Scale carefully: add rate limits and a small crawl loop
After one URL works, expand to a small list. Keep concurrency low, add delays, and stop quickly when error rates spike. This is the difference between a helpful tool and an accidental denial-of-service event.
- Handle edge cases with fallbacks
If a selector returns empty, try a backup strategy (another DOM path, a different tag, or a broader text extraction). The goal is graceful degradation, not perfect extraction on day one.
Even in AI News cycles, the best “agent” or pipeline often depends on plain data plumbing. A stable scraper becomes the boring foundation for smarter features.
Turn one page into a reusable AI-ready pipeline
The takeaway from KDnuggets’ Python-focused build is straightforward: get extraction working reliably, then add AI transformation on top. Build a simple scraper first, output structured JSON, and only then expand to multiple pages.
From the opening image—fan-blown silence in the room—you should end with repeatable results: consistent fields, clean text, and AI-ready inputs. If you keep your pipeline small and your logs clear, your next step is obvious: plug the extracted text into summarization, search, or QA workflows and expand coverage without breaking everything.
Related Articles
- US power grid AI bubble 2026: Build won’t be wasted
- Fireflies.ai Just Brought Its Meeting AI Into Your Inbox — And Your…
- V-Guard Unveils New Modular Switch Ranges Arizo and Xyro
FAQs: Troubleshooting a simple Python AI web scraper
Why does my scraper return empty content?
Most often, the CSS selector no longer matches or the page structure differs across URLs. Confirm by printing a small snippet of the parsed DOM (or saving the HTML to disk). Then update selectors and add a fallback extraction path.
How can I keep the scraper “simple” without losing quality?
Extract fewer fields at first and normalize aggressively: trim whitespace, remove navigation blocks, and keep only the main text. Once the output quality is stable, add the AI step (summary, tags, or classifications).
What’s the safest way to scale from one URL to many?
Start with a small URL list, add rate limiting, and monitor error rates. Stop scaling when you see access denials or abnormal response codes, then adjust headers, parsing logic, or crawl pacing.
Where should the AI step run in the pipeline?
After extraction and cleaning. If the AI step runs on noisy HTML or boilerplate, your summaries will reflect that noise. Keep the AI step deterministic by providing a consistent input format.
How do I comply with site rules?
Check robots.txt and the site’s Terms of Service before scraping. Also follow polite crawling practices: reasonable delays, limited concurrency, and caching when possible. Simple AI web scraper with Python
Was this article helpful?
Your feedback directly improves future articles on this site.