

NVIDIA has unveiled its most capable open multimodal model yet — the Nemotron 3 Nano Omni — and it could fundamentally change how AI agents are built. Announced on April 28, 2026, the model merges vision, audio, and language processing into a single unified system, replacing the clunky multi-model pipelines that slow down most AI agent workflows today.
If you have been following the rapid pace of AI hardware and software launches — including NVIDIA’s latest GPU roadmap updates and AI chipset developments in India — this one is a big deal.
What Is NVIDIA Nemotron 3 Nano Omni?
Most AI agent systems today use separate models for vision, speech, and text. Every time data passes between them, latency builds up and context gets fragmented. Nemotron 3 Nano Omni solves this by combining all three into one architecture.
The model is built on a 30B-A3B hybrid mixture-of-experts architecture with Conv3D and EVS encoders, supporting a 256K context window. It handles text, images, audio, video, documents, charts, and graphical interfaces — all as input — and outputs text responses.

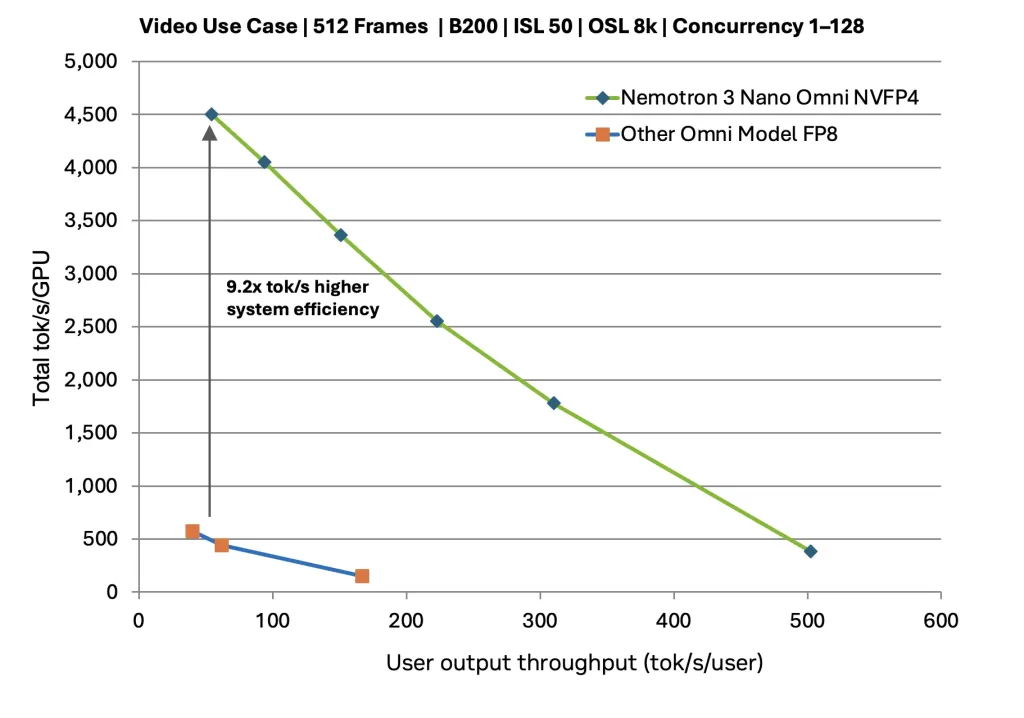
According to NVIDIA, the model delivers up to 9x higher throughput compared to other open omni models at the same interactivity level, while topping six leaderboards for complex document intelligence and video and audio understanding.
Key Specs at a Glance
| Feature | Details |
|---|---|
| Architecture | 30B-A3B Hybrid MoE, Conv3D + EVS |
| Context Window | 256K tokens |
| Inputs | Text, Image, Audio, Video, Documents, Charts, UI |
| Output | Text |
| Throughput Gain | Up to 9x vs other open omni models |
| Availability | Hugging Face, OpenRouter, build.nvidia.com, 25+ partners |
| Release Date | April 28, 2026 |
Three Core Use Cases
1. Computer Use Agents Nemotron 3 Nano Omni powers perception loops for agents navigating graphical user interfaces at a native resolution of 1920×1080 pixels, enabling high-fidelity visual reasoning across on-screen content. H Company has already integrated it into their computer-use agent.
2. Document Intelligence The model can parse PDFs, spreadsheets, tables, charts, and screenshots together — critical for enterprise compliance and financial analysis workflows where mixed-media inputs are the norm.
3. Audio and Video Understanding For customer service, research, and monitoring workflows, the model ties together what was said, shown, and documented into a single reasoning stream instead of producing disconnected summaries.
Who Is Already Using It?
Early adopters include Aible, Palantir, Foxconn, H Company, and India’s own Eka Care, which is building agentic multimodal healthcare applications using the model. Dell Technologies, Infosys, Oracle, and Docusign are among those actively evaluating it.
The Infosys and Eka Care adoption is particularly noteworthy for the Indian tech ecosystem — a sign that enterprise AI in India is moving well beyond chatbots.

Open Weights, Deploy Anywhere
Nemotron 3 Nano Omni is released with open weights, datasets, and training techniques, giving organisations full transparency and control. It can be deployed on edge hardware like NVIDIA Jetson, workstations like DGX Spark, or at data centre scale. The broader Nemotron 3 family has crossed 50 million downloads in the past year.
For developers, it is available now on Hugging Face and build.nvidia.com.
The Bottom Line
NVIDIA is not just selling GPUs anymore — it is building the full AI stack. Nemotron 3 Nano Omni makes multimodal agentic AI practical, affordable, and deployable without vendor lock-in. For developers and enterprises in India building the next generation of AI products, this open model is worth serious attention.
Stay tuned to TechnoSports for the latest in AI, tech, and gaming news.


