 SA329 (82.3 ov)
 AUS
 FLE1
 ARS1
 BAN
 WI
 IND-W
 ZIM-W
 GOA
 SC Delhi
 Milan
 Bologna
 Parma
 Udinese
 Venezia
 Inter Milan
 Genoa
 Juventus
 Monza
 Napoli
 ROMA4
 CAG2
 TOR1
 COMO3
 SAS2
 LAZ6
 AFG177
 ZIM140 (19.1/20 ov, target 178)
 AUCK
 CANT
 CD
 ND
 SIKM184
 NAGA187 & 46/4 (34 ov)
 JHK131/4 (47 ov)
 DELHI515/5d
 ODSA194
 SVCS13/0 (5 ov)
 BRODA616
 J & K6/0 (4 ov)
 CHD685/5d
 HP49/0 (14 ov)
 CGR216/8 (95 ov)
 AP231
 HYD193/2 (54 ov)
 PNJB431
 KNTKA297/7 (95 ov)
 TPURA194
 KER101/6 (35 ov)
 BENG350
 UAE
 OMA
 ENG
 SL
 DEN
 QAT
 KENYA
 KUW
 POA
 SPR
 BRB
 VAG
 PAK110
 NAM316/7
 IRE253 (44.5/50 ov, target 317)
 NZ198/3
 IND199/4 (13.2/20 ov, target 199)
 NED371/5
 JAB113 (19.3/20 ov, target 133)
 KAY132/9
 DON2
 EXT3
 MNR0
 AND2
 PEN1
 CLY1
 HUE1
 RAY1
 Gamba Osaka
 Buriram
 Kashima
 Pohang Steelers
 ABH0
 ALF1
 Sevilla2
 Osasuna0
 PSG2
 Lyon0
Optimizing vector database retrieval for ChatGPT context windows is crucial for maintaining performance as enterprise AI applications grow in 2026. Developers often face bottlenecks when massive datasets exceed the limited token capacity of current language models. Since there’s no confirmed
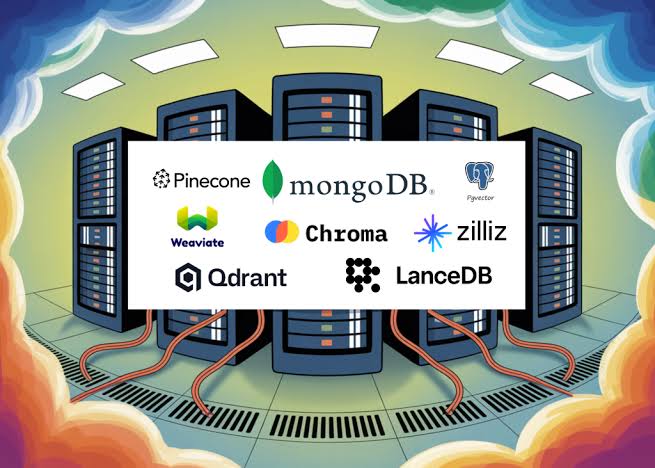
Vector database: Refining retrieval architecture for AI performance
Effective RAG (Retrieval-Augmented Generation) pipelines start with how you chunk and index your data. We’ve found that using a fixed-size chunking strategy often leads to semantic loss. On the other hand, recursive character splitting helps maintain the context needed for high-quality responses. When developers check out recent research on semantic search, the consensus is clear: metadata filtering matters just as much as the vector embedding itself. By pre-filtering metadata—like document category or timestamp—before doing a vector similarity search, you can significantly reduce the search space and boost the relevance of the retrieved context.
The big question is: how do you balance the number of retrieved chunks with the model’s token limits? A common mistake is injecting too many raw chunks into the context window, which can dilute the model’s attention mechanism.
We suggest implementing a re-ranking layer after the initial vector search. Using a cross-encoder model to score the relevance of retrieved chunks ensures that only the most pertinent information reaches the generative engine. This keeps the context window lean and reduces the risk of hallucinations during complex query resolution.
Scaling vector infrastructure for enterprise deployments
Building a solid pipeline requires careful hardware and software consideration. However, no specific official specs like RAM, storage, or processor requirements are provided for these specialized setups.
That said, the underlying infrastructure must support high-concurrency read operations. We recommend utilizing hybrid search techniques that mix dense vector embeddings with sparse keyword-based search (BM25). This dual-path retrieval captures both the semantic intent of a user’s query and the specific technical terminology that vector models sometimes overlook.
What’s actually happening in production environments is a shift toward persistent caching of common query results. By storing the top-K retrieved documents for frequently asked questions, you can skip the vector search entirely for some incoming traffic. This approach reduces costs and significantly improves response times. As you refine your architectural patterns for AI, make sure your vector database supports horizontal scaling to handle the spikes in demand that are typical of modern enterprise workflows. Always test your retrieval pipeline against diverse datasets to catch potential drift in embedding quality over time.
The future of AI interaction hinges on how efficiently we connect static data to dynamic reasoning engines. Focus on re-ranking and hybrid search to ensure your context windows stay high-signal and low-noise.
FAQs
How does hybrid search improve retrieval accuracy?
Hybrid search combines vector similarity with BM25 keyword matching, ensuring that both broad conceptual queries and specific technical terms are captured effectively.
What is the advantage of using a re-ranking layer?
A re-ranking layer scores the top results from your vector search, making sure that only the most contextually relevant information gets passed to the language model, preventing token wastage.
Can metadata filtering reduce latency?
Yes, pre-filtering by metadata limits the search to a relevant subset of your database, which drastically cuts down the processing time needed for similarity calculations.


