
 NZ121/3 (15.1/20 ov)
 IND
 NAM49/2 (10.5/50 ov)
 IRE
 MOZ
 UGA
 AVL
 MNC
 RAY
 ELC
 GMB
 ZMB
 NGA
 LES
 CAG
 BOL
 COMO
 SAS
 FCA
 FCU
 Ipswich1
 Nottm Forest1
 Alavés1
 Málaga1
 Torino3
 Monza2
 Brest1
 Nice2
 WA
 NSW199/3 (31/50 ov)
 DEN
 KUW
 KENYA
 QAT
 SWD-W
 EPR-W
 TTN-W
 WPR-W
 NZ-A135/3 (41 ov)
 IND-A113
 DHA
 RAJ
 MYMS
 CHATT
 RAN
 BAR
 SYL
 KHU
 MEX-W
 ARG-W
 UAE
 NED
 PAK
 ENG
 IND-W
 ZIM-W
 AFG170/3 (34.3/50 ov, target 170)
 ZIM169
 TAS137 (25.2/35 ov, target 276)
 VIC304/7 (50 ov)
 CHE0
 DYI0
 CHO1
 QIN0
 HEN1
 BEI0
 LIA1
 ZHE0
 QWC1
 YUN0
 SHX0
 Shanghai Shenh0
 TIG0
 SHP0
 WTT1
 SHT3
 KOE
 S04
 M05
 SVW
 RBL
 ELV
 Stuttgart2
 Gladbach3
 Al Ahli4
 Al Khaleej1
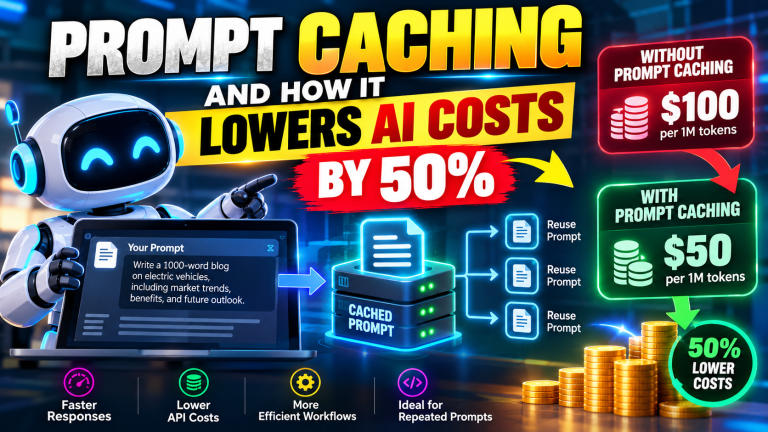
On August 5, 2024, OpenAI announced prompt caching support for GPT-4o and GPT-4o-mini. The impact is immediate: input token costs can drop by up to 50%, with cached tokens typically earning a 90% discount across major API platforms.
What is prompt caching, and why does it lower AI API costs?
Prompt caching stores repeated parts of an API request, so the model does not process identical input at the full Cached input tokens typically earn a 90% discount, capping overall cost reductions at 50%. If an application sends the same large set of instructions across hundreds of requests, the cached portion can qualify for discounted pricing while only new or changed input is charged at the standard rate.
The headline figures need careful reading. A 90% discount applies to eligible cached input tokens, while a total input-cost reduction of up to 50% depends on how much of each request is repeated. A request with little reusable context will save less than one built around a large, stable prompt.
Does the caching require developers to manage a cache manually?
No. OpenAI automatically applies the caching to requests exceeding 1024 tokens, so developers do not need to create or refresh a cache themselves for supported models. The system identifies reusable prompt content and applies the relevant treatment within the API workflow. Requests exceeding 1024 tokens trigger automatic caching, removing manual overhead.
Stable instructions should appear before changing user data, because a constantly changing prefix can reduce the amount of context that qualifies for reuse. This distinction matters for AI agents. An agent that changes its entire prompt on every turn may gain little from caching, while one that keeps its policies, tool descriptions, and reference material stable can repeatedly reuse those sections. Our earlier reporting on prompt-driven outages also shows why cost controls should sit alongside careful prompt design.
How does Anthropic the caching differ from OpenAI’s approach?
Anthropic introduced the caching for Claude models on August 13, 2024. Its API requires a minimum cacheable block size of 1024 tokens for Claude 3.5 Sonnet and Claude 3 Haiku, making short prompts ineligible for the feature. Claude 3.5 Sonnet and Claude 3 Haiku require a strict 1024-token minimum block size.
Developers must identify a sufficiently large repeated section, such as a knowledge base or tool definition, rather than expecting every instruction to receive a discount. Anthropic’s cache retention period also expires after 5 minutes of inactivity unless a new request refreshes it. That window suits active conversations and bursts of application traffic, but it may provide less value for infrequent requests. The distinction complements broader work on context caching in retrieval systems, where repeated reference material can otherwise inflate every API call.
Is it useful only for large companies?
No. Small teams can benefit when their applications send repeated instructions, documentation, or structured data, although the absolute saving depends on request volume and prompt size. A customer-support bot with a stable policy document has a clearer caching opportunity than a simple chatbot sending short, unique questions.
Applications with high request volumes may see the fastest ROI from stable context. Examples include coding assistants, document-analysis tools, retrieval-augmented generation systems, and multi-step agents that call a model several times during one task. What should developers measure? They should track cache-hit rates, repeated token volume, request frequency, and the split between cached and uncached input. this is a pricing feature, not a substitute for trimming irrelevant context or selecting a less expensive model.
What should developers expect next from the model?
this option is likely to become a standard cost-control layer as AI applications move from one-off questions to persistent agents. The key design decision will be sepaFuture savings will depend more on application architecture than on headline discounts of 50% or 90%.
Teams comparing providers should examine cache thresholds, retention rules, supported models, and billing dashboards rather than relying on a single discount figure. They should also account for latency and cache invalidation when source documents change. As platforms expand caching controls, developers will gain more ways to balance freshness, cost, and consistency. The practical winner will be the application that sends less repeated context while preserving the information the model actually needs. the product is not magic: it rewards stable prompts, frequent requests, and disciplined token design.. For more detail, see VentureBeat AI.
FAQs
Does the caching reduce output token costs?
No. the caching primarily reduces the cost of eligible repeated input tokens. Output tokens remain subject to the model’s normal pricing.
What is the biggest the caching myth?
The biggest myth is that every API request becomes 90% cheaper. The discount applies to cached input tokens, while the overall saving depends on the proportion of the request that is repeated.
Can short prompts use Anthropic the caching?
Anthropic requires a minimum block size of 1024 tokens for Claude 3.5 Sonnet and Claude 3 Haiku. Shorter cacheable blocks do not meet that stated threshold.
How long does Anthropic the caching last?
Anthropic’s API cache expires after 5 minutes of inactivity unless a new request refreshes it. Applications with longer gaps should not assume that previously cached context remains available.
Was this article helpful?
Your feedback directly improves future articles on this site.




