 WI-A
 LIONS
 ELC0
 VAL1
 ACV0
 RAFC1
 MAR0
 CDSC1
 JUV
 NAP
 OLM
 TOU
 ATH
 RSO
 NED
 OMA
 Sassuolo
 Fiorentina
 Atalanta
 Parma
 Lorient
 Brest
 Newcastle
 Everton
 LEC1
 GEN2
 LIV0
 ARS1
 SGE3
 HSV1
 LYON2
 ANG0
 NZ-A218/3 (62 ov)
 IND-A346
 QLD202/5 (71 ov)
 VIC307
 SYL218 & 89/2 (38 ov)
 CHATT210
 MYMS108 & 57/2 (14 ov) (f/o)
 KHU288
 DHA
 BAR
 RAN122/3 (39 ov)
 RAJ231
 MS-W
 PS-W
 MOW
 BRB
 KAY
 KAG
 CHR
 SPR
 BIK
 JAB
 ASSAM
 KNTKA
 TPURA
 SAU
 AFG81/3 (8.1/20 ov, target 80)
 ZIM79
 NAM131/5 (21.2/50 ov, target 130)
 IRE129
 NZ195/3 (18/20 ov, target 192)
 IND191/8
 PAK331/7 (48.3/50 ov, target 326)
 SL325/8
 SS-W196/8
 HH-W109 (17.4/20 ov, target 197)
 ST-W180/4 (16.4/20 ov, target 179)
 BH-W178/5
 LOM0
 GENT0
 CHN1
 BRA0
 NGA0
 VEN0
 SEV1
 RMA1
 CHA2
 RLL0
 Deportivo
 Osasuna
 PAR3
 MON1
 RAC0
 RMA3

Why Single-Vendor GPU Fleets Became a Bottleneck
For years, artificial intelligence ran on one dominant architecture. Training large language models meant sourcing thousands of graphics processing units from a single manufacturer. Enterprises expanded their fleets with identical silicon, which simplified engineering pipelines but created serious bottlenecks when demand peaked.
Supply-chain friction left developers waiting months for delivery allocations even as research timelines tightened. Every breakthrough in model scaling added pressure to primary vendors’ manufacturing facilities, while companies adapted their software stacks to proprietary instruction sets instead of standardizing across architectures. We track how these rigid procurement cycles historically capped independent startup growth rates.
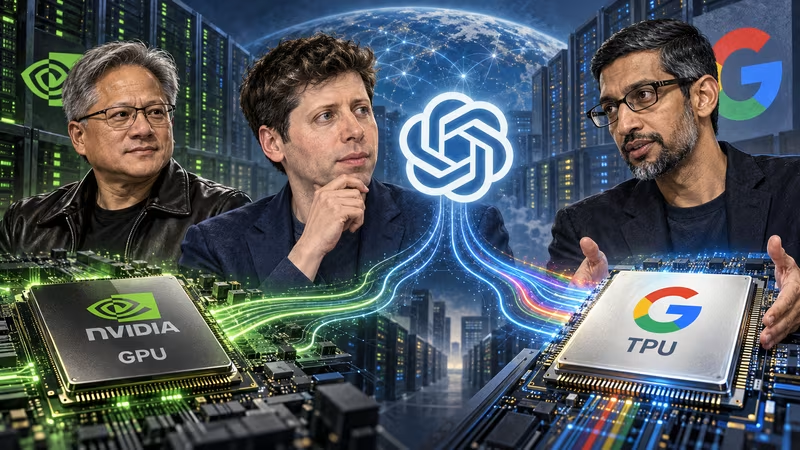
OpenAI’s Google TPU Pledge and the Q2 2027 Timeline
That pattern shifted when the chatbot developer formalized a cross-vendor procurement agreement. Reports suggest the proposed purchase involves specialized tensor processing units designed for next-generation model training. These custom silicon modules are expected to include high-bandwidth memory capacities that exceed existing industry benchmarks.
Reports put the processors’ deployment within the company’s infrastructure in the second quarter of 2027. Financial terms remain officially undisclosed, though industry observers expect multi-year volume commitments. This move responds to rising energy consumption and physical space limitations in traditional data centers; engineers could spread workloads across heterogeneous systems to improve performance per watt and reduce single-point failure risks. The transition could reportedly create earlier pathways for integration with TSMC (Taiwan Semiconductor Manufacturing Company) and NVIDIA manufacturing processes.
How Alphabet’s TPU Sales Pressure NVIDIA
Competitors have watched the semiconductor market consolidate around proprietary ecosystems for years. Alphabet has gradually expanded commercial sales of its processors, giving external clients access to hardware once reserved for internal search operations. This wider availability pushes established vendors to innovate faster or risk losing institutional contracts. Software teams now have to maintain parallel optimization pipelines for competing instruction sets, adding upfront development work but building long-term resilience.
Researchers’ benchmark results on the OpenAI Blog reportedly show that cross-platform compatibility speeds up algorithmic refinement; the OpenAI RSS feed also offers additional architectural deep dives. Meanwhile, cloud providers are redesigning rack layouts for mixed-architecture deployments, fundamentally changing colocation pricing structures. Developers tracking reportedly available NVIDIA Google A5X architectural comparisons note that hybrid environments need sophisticated workload schedulers to balance latency and throughput. That competitive pressure ultimately benefits downstream applications and lowers subscription barriers for smaller ventures, while app developers watching available BEST Google Play storefront updates see similar consolidation patterns driving platform-wide optimizations.
Deployment Roadmap: What Engineering Teams Must Change
Organizations preparing for this transition should assess their software dependencies before committing to new hardware pipelines. Mixed-architecture environments need updated compiler toolchains and memory management utilities to prevent performance losses during cross-device transfers. The comparison below outlines the main operational differences between the legacy single-source approach and the emerging diversified framework.
| Metric | Legacy Single-Source Architecture | Emerging Diversified Framework |
|---|---|---|
| Procurement Strategy | Exclusive vendor allocation agreements | Multi-vendor volume purchasing |
| Memory | Standardized industry baselines | above-industry-standard HBM capacity |
| Deployment Timeline | Quarterly batch deliveries | Phased rollout beginning Q2 2027 |
| Software Optimization | Vendor-specific instruction tuning |
Read Next
- ONDC DigiDukaan: How India’s 1.4 Crore Kiranas Are Going Digital, One Restock at a Time
- How Much is Microsoft Net Worth as of 2026?
- Amazon Gift Card Codes: Free Gift Card as of November 2026
FAQs
Why is OpenAI buying Google AI chips?
The move could help OpenAI spread workloads across different systems, improve performance per watt and reduce single-point failure risks.
When are Google TPUs expected to be deployed at OpenAI?
The text says the processors are expected to be deployed in OpenAI’s infrastructure in the second quarter of 2027.
What are the drawbacks of using different AI chips?
Software teams may need to maintain separate optimization pipelines for competing instruction sets, adding upfront development work.
Was this article helpful?
Your feedback directly improves future articles on this site.