NZ
 IND
 NAM
 IRE
 MOZ
 UGA
 Aston Villa
 Man City
 Rayo
 Elche
 GMB
 ZMB
 NGA
 LES
 Cagliari
 Bologna
 IPS1
 NFO1
 ALA1
 MCF1
 TOR3
 MON2
 BRE1
 NICE2
 TAS67/4 (15.4/50 ov, target 305)
 VIC304/7
 NZ-A135/3 (41 ov)
 IND-A113
 DHA
 RAJ
 MYMS
 CHATT
 RAN
 BAR
 SYL
 KHU
 UAE
 NED
 PAK
 ENG
 IND-W
 ZIM-W
 AFG170/3 (34.3/50 ov, target 170)
 ZIM169
 DOLPH56/0 (3.5/8 ov, target 56)
 SWD51/4 (8/8 ov)
 WSW1
 BRI1
 Como
 Sassuolo
 Augsburg
 Union Berlin
 Cologne
 Schalke
 Mainz
 Bremen
 RB Leipzig
 Elversberg
 VFB2
 BMG3
 AHL4
 KHA1
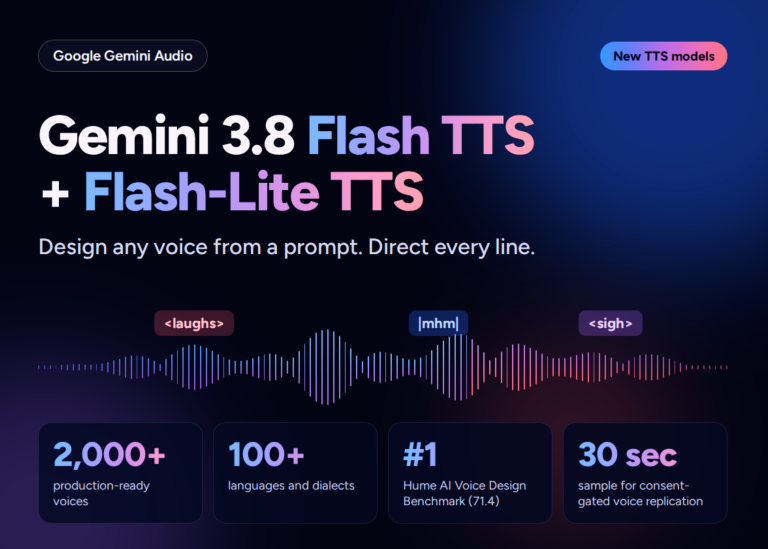
The context behind google launches gemini shapes how this story lands. On Friday, September 25, 2026, Google officially announced the Gemini 3.8 Flash TTS models. The release reshapes real-time speech synthesis benchmarks overnight, delivering significantly tighter latency controls alongside a native voice cloning pipeline that lets creators dial in specific acoustic profiles without heavy training cycles.
Processing throughput reportedly hits eighty-five tokens per second, giving live streaming platforms and automated customer service bots the responsiveness they have chased for years. The commercial rollout pairs that speed with a straightforward metered billing structure. The base API pricing for Gemini 3.8 Flash TTS is reportedly set at $0.07 per 1 million characters, positioning the service firmly below legacy enterprise speech providers while leaving room for volume discounts at scale. Engineering leaders can now route high-concurrency voice generation through a single unified endpoint rather than juggling fragmented text-to-speech vendors.
Google Launches Gemini: Engineered Voice Synthesis and Control
The headline capability centers on granular vocal manipulation. Creators can upload short reference recordings and extract a digital voice profile that maintains consistent pitch, cadence, and breathing patterns across long-form outputs. Audio engineers retain direct access to prosody sliders, allowing precise adjustments to emotional tone, pacing, and emphasis without regeneration. Launches CREST Google integration; audio layers blend directly into visual interfaces without perceptible sync drift.
Local Deployment Requirements And Hardware Limits
Running the model offline requires meeting specific hardware thresholds. The recommended minimum RAM for local deployment of the Gemini 3.8 Flash TTS client is reportedly 16 GB, ensuring stable inference during batch processing or concurrent user sessions. Storage footprint stays manageable, with the core model weights reportedly occupying just 4.5 GB, making distribution straightforward for edge devices and mid-range workstations.
| Metric Category | Specification |
|---|---|
| Processing Speed | Reportedly 85 tokens per second |
| Minimum RAM Requirement | Reportedly 16 GB |
| Core Model Weight Size | Reportedly 4.5 GB |
| Base API Pricing | Reportedly $0.07 per 1 million characters |
Edge deployments benefit from the compact weight design, though memory bandwidth remains the primary bottleneck for sub-second generation targets. Teams planning on-premise rollouts should verify PCIe lane availability and thermal headroom before scaling cluster nodes. Infrastructure managers often compare these constraints against alternatives like the Jensen Control Models frameworks when evaluating total cost of ownership.
Market Positioning And Next Steps
The announcement shifts the competitive landscape toward faster, cheaper, and more controllable speech synthesis. Competitors relying on static waveform databases must now adapt their generation stacks to match the dynamic prosody controls introduced this week. Content creators and software developers alike gain a standardized toolkit that reduces manual post-production editing while expanding creative possibilities.
Security protocols remain aligned with ongoing industry discussions, echoing concerns highlighted by the former Google Safety Chief regarding synthetic media verification. Organizations planning production migrations should monitor upcoming SDK patches and benchmark updates over the next quarter. As the ecosystem matures, expect third-party plugin ecosystems to standardize around this voice control interface. It is worth watching how Google Launches Gemini develops from here.
Audio generation just became cheaper, faster, and fully tunable. Track the SDK releases to deploy cleanly before competitors catch up.
FAQs
What makes the new voice creation feature different from older synthesis tools?
The updated engine extracts full acoustic profiles from brief recordings and applies real-time prosody sliders, eliminating hours of manual training or studio booking.
Can developers run the model locally without cloud dependencies?
Yes, provided your workstation meets the sixteen gigabyte RAM threshold and reserves four point five gigabytes of storage for the core weights.
How does the pricing model compare to enterprise speech vendors?
At seven cents per million characters, the tier sits significantly lower than traditional voice APIs while matching processing speeds for live applications. Source: Gadgets360
Was this article helpful?
Your feedback directly improves future articles on this site.