BAN88/3 (40 ov)
 WI356
 AFG106/1 (32.5 ov)
 ZIM504
 FC Goa
 BFC
 HSV
 BMG
 VEN
 UDI
 TOU
 STR
 EVE
 COV
 SEV
 ALA
 NZ
 IND
 Inter Kashi
 SC Delhi
 AZ Alkmaar1
 Juventus2
 Leverkusen0
 Marseille1
 Benfica3
 Lech Poznan1
 Celta Vigo1
 Union SG2
 MOUNT198
 ROCKS101/2 (22.1/50 ov, target 199)
 TUSK85/1 (21.1/50 ov, target 245)
 RHINO244
 CHR151/6 (20 ov)
 POA
 RWA-W
 USA-W
 DMJIR290 & 134/5 (46 ov) (f/o)
 HYD-R519/8d
 FSLB259 & 54/1 (26 ov) (f/o)
 PRB503/4d
 ZIM-A154/4 (49.2 ov)
 IRE-A424
 WI-A
 LIONS
 MR-W
 AS-W
 BH-W
 HH-W
 EASTN
 DOLPH
 NAM-W
 DOL-W
 LIO-W
 EPR-W
 TTN-W
 MS-W159/7 (20 ov, target 161)
 SS-W160/5
 ST-W166 (19/20 ov, target 184)
 PS-W183/3
 KAY137/7 (20 ov, target 177)
 SPR176/6
 UGA-W74/6 (19.3/20 ov, target 74)
 WAR138/7 (20 ov)
 BOL138/5
 Leeds
 Spurs
 Celtic3
 Besiktas2
 Hapoel Be'er0
 OFI Crete2

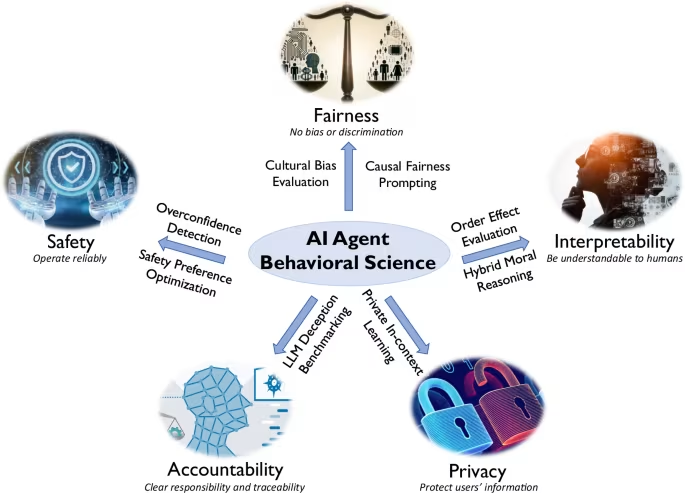
Autonomous AI agents aim to tackle complex tasks, but a recent study finds that they systematically diverge from human preferences when formalizing mathematical proofs. Posted to arXiv on November 3, 2026, the paper by Bálint Gyevnár and Simon DeDeo points to a critical gap: agents favor different structural cues than mathematicians and often smooth out unconventional but insightful proof paths.
November 2026: A Study of Proof-Making Choices
The paper introduces “simulated collaboration” to compare the next steps AI agents favor with the choices humans make while constructing proofs. Instead of treating a proof as simply finished or unfinished, the researchers look at which parts draw attention and how those choices shift as work progresses. That distinction matters: a proof can be correct, yet its route through the problem may be hard for someone to follow.
The researchers reportedly analyze 9 major human collaborations in Lean, covering 4.7 million definitions across more than 6,000 commits. Their findings describe recurring differences in attention, not one universal failure rate. In the arXiv paper, they report that agents are more drawn to explicitly marked gaps than humans, less drawn to densely connected proof centers and complex or surprising goals, and more attracted to surprising proof bodies, which they tend to regularize toward a baseline. That contrast is revealing. An agent may gravitate toward an unusual proof construction, then make it more conventional. For mathematicians, the unusual route can offer useful insight; smoothing it away may leave a valid result while obscuring how a person reached it.
The Evaluation Details and Their Limits
A separate fact sheet supplied with the story describes a formalization benchmark with 1,250 mathematical problems from international competitions. It also lists evaluation servers with 80 GB of HBM3e VRAM per GPU. Those details don’t appear in the arXiv abstract, so they shouldn’t be treated as confirmed specifications for the study described there.
The same caution applies to the claim that divergence metrics exceeded 40%. The available abstract reports behavioral patterns, but gives neither that percentage nor a definition of the metric behind it. That distinction matters: “divergence” here describes differences in preferred proof steps, not necessarily a measured rate of incorrect proofs. Instead, the paper’s central evidence comes from collaborative Lean projects and the researchers’ method for comparing human and agent choices. Its scale lets the authors study behavior across many definitions and commits. But that alone doesn’t establish that every agent or mathematical task will show the same pattern.
Why Human Preferences Matter in Formal Verification
Formal proof systems such as Lean and Coq make mathematical claims precise enough for automated checking. But a checkable endpoint is only part of the work. When an AI agent produces or edits a proof, people may also need to understand its structure, spot a surprising idea, and decide whether the route can support further reasoning.
The findings point to a tension between local progress and human legibility. Explicit gaps can seem like clear invitations to act, while a highly connected proof center may be harder to choose as the next target. If agents favor obvious openings and avoid complex goals, they may make different choices from collaborators willing to work through a difficult or unexpected step. That doesn’t show that agent-produced proofs are invalid. It suggests that correctness and collaboration quality are separate questions. As automated systems generate more proof material, researchers and developers will need ways to judge not only whether a proof checks, but also whether people can understand its construction and whether it preserves meaningful mathematical choices.
What Researchers May Examine Next
The paper identifies possible blind spots and suggests interventions for future human-AI work, but the abstract doesn’t specify a particular product change or deployment plan. One natural next step is to test whether agents can be guided to attend more to proof structure and difficult goals, instead of simply choosing the most visibly open task.
Such evaluations would need to separate a genuinely helpful intervention from one that merely changes how an agent’s choices appear. For teams building formal verification tools, the findings make evaluation design more important. A benchmark that records only completed proofs could miss whether an agent regularly sidesteps complex goals or normalizes surprising constructions. Researchers can use collaboration traces to ask a harder question: does the system help people reason, or just produce work that a checker accepts? The next test for autonomous AI agents isn’t just whether they can finish proofs, but whether people can follow the choices that get them there.
Read Next
- Samsung Android XR Smart Glasses Pre-Orders Start November 12
- Claude Personal Finance Tool Can Analyze Your Spending
- iPhone Duo Durability Test Passes 260,000 Folds on Livestream
FAQs
Do autonomous AI agents produce incorrect mathematical proofs?
The study describes differences in preferred proof steps, not a measured rate of incorrect proofs. A proof can be correct even when its route is hard for someone to follow.
Which proof system does the study examine?
The researchers analyze human collaborations in Lean. The text also mentions Coq as an example of a formal proof system.
Does the study confirm a 40% divergence rate?
No. The available abstract reports behavioral patterns but gives neither the 40% figure nor a definition of the metric behind it.
Was this article helpful?
Your feedback directly improves future articles on this site.